BankruptWatch
A bankruptcy risk classifier rebuilt after discovering the original 'accuracy' claim didn't match what the code actually did.
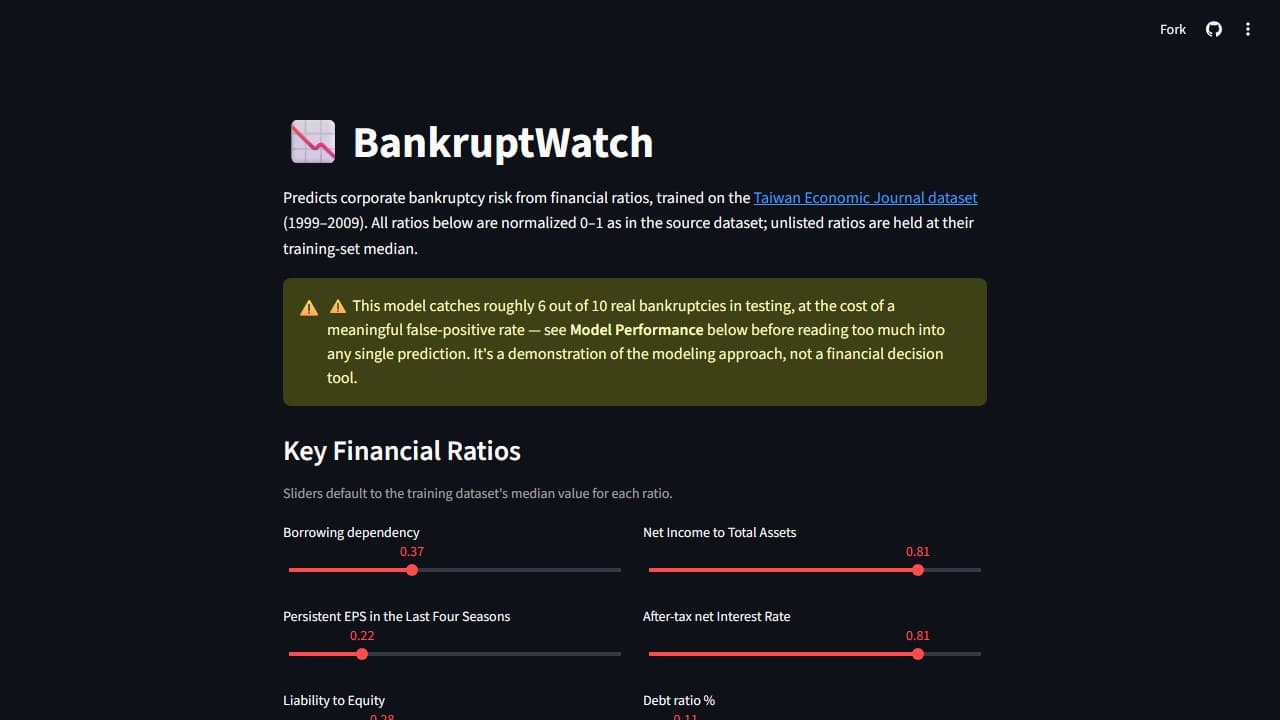
Overview
A classifier that predicts corporate bankruptcy risk from financial statement features. This project became a lesson in not trusting a headline metric just because it's written in a README.
What I found and fixed
The original notebook claimed a 92% accuracy figure. On inspection, that number didn't correspond to anything the notebook actually did — SMOTE oversampling was computed but never actually used in training, and the reported metric didn't reflect real held-out performance on the minority (bankrupt) class.
I rebuilt the training pipeline correctly. The honest result: 57% recall on actual bankruptcies, versus 0% for a naive baseline — a much more useful (and true) number than the original claim, even though it's less flattering.
Technologies Used
- Python, scikit-learn — Random Forest, AdaBoost, SMOTE
- Pandas / NumPy — feature engineering on the TEJ dataset
- Streamlit — deployed demo