KlasifikasiSentimenTwitter
Naïve Bayes hate-speech classifier for Twitter/X comments, published in the Journal of Informatics and Science Media (JISMEDIA).
− README overstated what the deployed model could do
− no recall analysis — accuracy only
+ accuracy 84 → 83%, a deliberate trade
+ hate-speech recall 0.14 → 0.18
Overview
A Multinomial Naïve Bayes classifier detecting hate speech against Islam in Indonesian-language tweets. The underlying research was published in the Journal of Informatics and Science Media (JISMEDIA), Vol. 1 No. 2, pp. 34–41, December 2024 (ISSN 3064-1942). The repository had been sitting in a buried folder with a README that overstated what the deployed model could actually do.
What I fixed
- Promoted the project out of a nested folder into its own repo.
- Corrected a factually wrong README claim (an unverifiable "92%"-style headline number that didn't match the notebook).
- Deliberately deployed the config that trades accuracy for recall on the minority (hate-speech) class: 18% recall / 83% accuracy (alpha=2.0, 80/20 split), instead of the highest-accuracy config, which scores 84% accuracy but only 14% recall — a hate-speech filter that catches 1 in 7 real cases isn't a useful filter, regardless of its accuracy score.
Technologies Used
- Python, scikit-learn — Naïve Bayes classifier
- NLP preprocessing for social media text
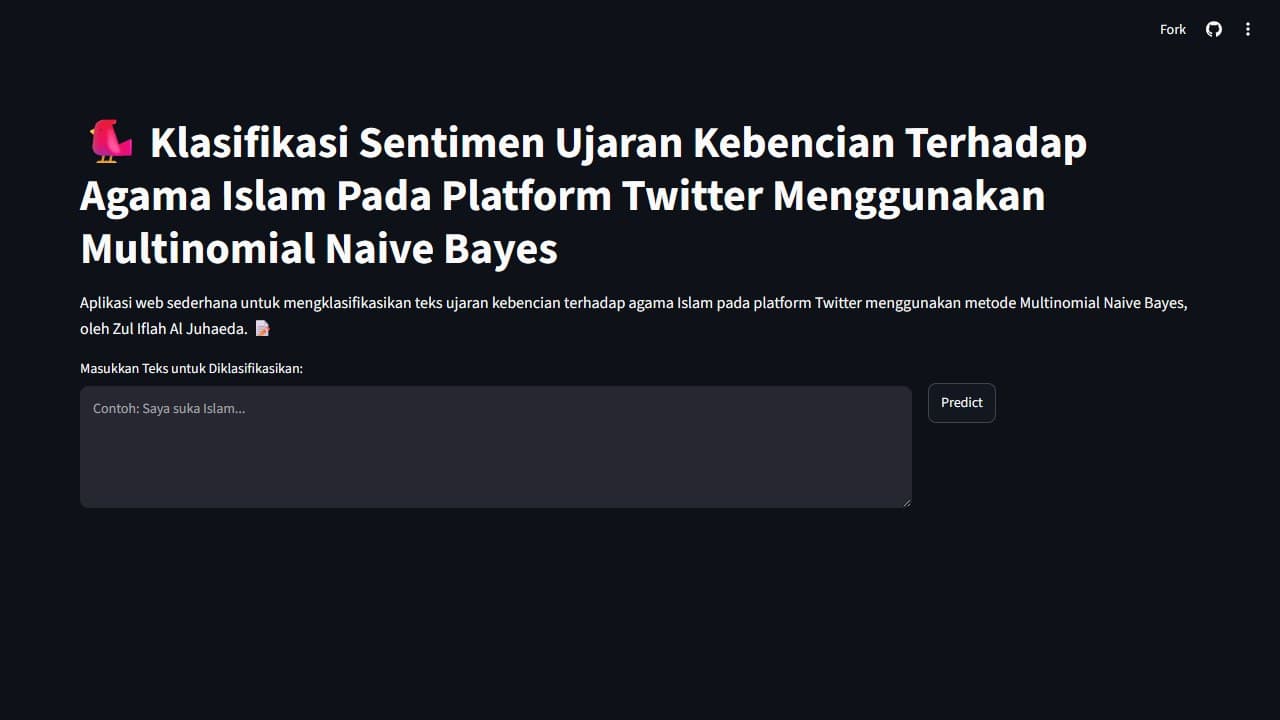
- Streamlit — deployed demo